A Signature Hidden in Word Choice
A student hands in an essay that ChatGPT wrote. Reading it, the teacher sees nothing unusual. Now imagine that every word in it was chosen with a tiny, invisible tilt toward a secret list, and that a machine holding the list can count the tilt. That is how one well-known kind of AI watermark in text works, and on 5 October OpenAI said it would start adding one to ChatGPT and Codex output for users in the European Union.
Then the student replaces a quarter of the words with synonyms. In OpenAI’s own test on 400-token passages, that drops detection to about 17%. This piece explains the signature that lives in a model’s word choices, why it is so easy to wipe, and what that means for AI-generated content detection in classrooms and hiring.
Why AI Text Detection Moved to Watermarks
The first generation of AI detectors guessed after the fact, scoring how “AI-like” a text read. They did badly enough that OpenAI withdrew its own classifier in July 2023, citing its “low rate of accuracy”: it had caught 26% of AI text while wrongly flagging 9% of human writing. A Stanford study in Patterns the same year found seven popular detectors labelled essays by non-native English writers as AI-generated 61% of the time on average.
So the idea shifted from guessing to marking. A language model writes in tokens, small chunks of words, and at every step it holds a probability table of candidate next tokens and picks one. If the model leaves a statistical mark while it picks, the mark can be checked later without judging style at all.
Then regulation added a push. The EU AI Act, the European Union’s law that regulates AI systems by risk, requires providers of generative AI to make their output detectable as AI-generated, from 2 August 2026. OpenAI is launching the text watermark by default only in the EU and making it opt-in for API customers elsewhere, an order that suggests compliance is a large part of the motive.
What Is an AI Text Watermark, and How Is It Detected?
An invisible watermark in text is neither hidden characters nor a line saying “written by AI”. It lives in the habits of word choice. A person reads the text normally; only someone with the detection method can see that the choices are too consistent to be chance. OpenAI has not published how its method, called textGrain, works beyond saying it “slightly changes the model’s word choices”. Still, the best-known public design shows the principle.
The green-list watermark, step by step
From Kirchenbauer et al., “A Watermark for Large Language Models” (ICML 2023). OpenAI’s method may differ.
- Draw lots from the previous wordBefore each new token, the token before it is combined with a secret key and hashed into a lottery number.
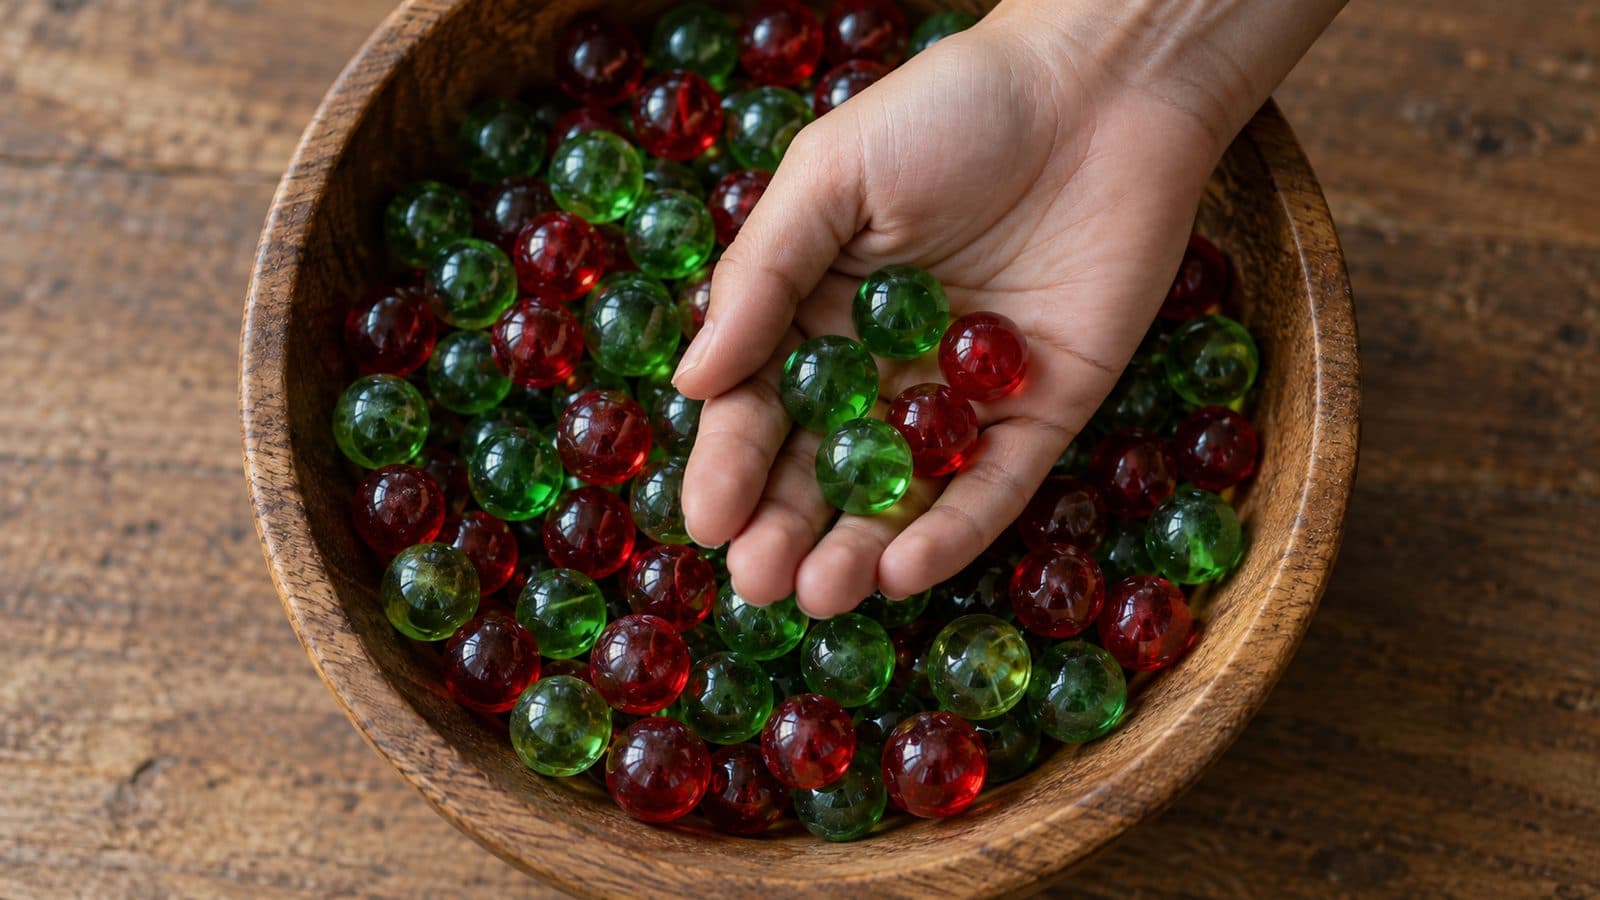
- Split the vocabularyThat number divides every possible next token into a green list and a red list, about half each.
- Nudge toward greenGreen tokens get a small extra score, so the model picks them a little more often. Any single choice still looks natural.
- Count at detection timeA detector holding the key re-runs the same hash on the text, counts the green tokens, and measures how far the share sits above the roughly 50% that chance would give.
The detector turns that excess into a score (a z-score) that grows with length, then compares it with a threshold. A “1% false-positive target” means the threshold is set so that about 1 in 100 unwatermarked passages would still cross it by chance. Raise the threshold and fewer innocent texts get flagged, but more watermarked ones slip through. Length matters most: ten words cannot prove a bias; four hundred can. OpenAI’s own figures show it. The detection rate, the share of watermarked passages the detector correctly flags, was about 80% for unedited text at 200 tokens and about 95% at 400 tokens, with the threshold set so about 1% of unwatermarked text would be wrongly flagged, according to BleepingComputer. Google DeepMind published a different approach, SynthID Text, in Nature in 2024 and open-sourced it; that paper also acknowledges the mark weakens after heavy rewriting.
What OpenAI Announced, and What It Left Open
“Over the coming weeks, we will add an invisible watermark to eligible ChatGPT and Codex text output in the European Union,” OpenAI wrote on 5 October, as quoted by BleepingComputer. It covers users on all plans, but only in the EU; OpenAI told TechCrunch it is “not making text watermarking a global default at launch.” API customers anywhere can switch it on for select models; it is off by default.
The detector is not public: access is “initially limited to approved researchers and expert organizations”. It also published its own stress test. Replacing 10% of words with synonyms cut detection from a baseline of about 92% in that test to 66%; replacing 25% cut it to 17%. Short, edited or translated text, OpenAI says, may not be detected reliably, and a missing watermark “does not prove human authorship.”
Several things are not public: whether textGrain uses green lists or something else, its false-positive rate in everyday use, who beyond researchers will get the detector, and whether watermarking will spread outside the EU.
Why Does Rewriting Erase an AI Watermark?
In a green-list scheme, whether a word counts as green depends on the word before it. Change one word and two things happen: its colour is re-rolled, and so is the lottery number for the word after it. With the previous word as the only input, each swap can disturb two scored words, so replacing a quarter of the words can disturb up to about half. The survivors still lean green, but over 400 tokens the score usually falls below the threshold; in OpenAI’s test about 17% of passages still cleared it. Its inventors made the same point about its own design: removing the mark “requires modifying roughly one quarter of the tokens or more.”
Translation is the extreme case: every original word disappears. Back in August 2024, OpenAI said as much when it held back an earlier watermark. That method, it wrote, was effective against “localized tampering, such as paraphrasing” but “less robust against globalized tampering; like using translation systems, rewording with another generative model,” as TechCrunch reported. Earlier, the Wall Street Journal had reported internal documents calling it “99.9% effective” on enough unedited text. That was a different method; OpenAI’s 2026 numbers show synonym swaps do weaken textGrain.
Compliance, Abuse and Tracing Need Different Watermarks
The three reasons to mark text ask very different things of the mark, which is why the same 17% can be a footnote or a failure.
Three purposes, three bars
Our reading of what each purpose needs.
| Purpose | What it needs | Does the 17% result hurt? |
|---|---|---|
| Compliance | A working, documented means of marking and detection | Little |
| Abuse prevention | A mark that survives deliberate editing | Badly |
| Tracing your own output | Very few false positives on near-verbatim text | Little |
Why a stronger mark costs quality
The heavier the nudge toward green words, the easier the mark is to detect and the harder to wash out, and the more often the model picks a slightly worse word to hit the list. A light nudge keeps the writing natural but fades under light editing. Any provider has to choose a point on that curve, so a mark that weakens when edited follows directly from that trade-off.
Erasing it is cheap
Synonym swaps, a second model rewriting the text, or a round trip through another language all cost almost nothing. People who want to deceive will learn these tricks first. Our expectation is that the people a watermark catches will mostly be ordinary users who pasted text unchanged, which is the opposite of who abuse prevention is meant to stop.
What compliance actually asks for
The EU AI Act’s Article 50(2) asks providers to mark output “in a machine-readable format and detectable as artificially generated”, with solutions that are “effective, interoperable, robust and reliable as far as this is technically feasible.” Read plainly, that is a duty to provide a means of detection, limited by what is technically feasible. For that purpose a 17% result after heavy editing matters much less than it does for stopping cheating or fraud. So one number is a minor caveat for compliance and close to fatal for abuse prevention.
What a watermark can tell a tracer
A watermark can support the claim “this passage came from our model largely unchanged.” It cannot say who prompted it or what they used it for. And it works in one direction only: finding no mark does not show a human wrote the text, as OpenAI itself says.
Ecosystem: one lock, many doors
If one provider marks its text and others do not, a user who wants unmarked text switches tools or runs an open-weight model locally. Watermarks only add up to something if many providers mark their output and detection works across them. The EU’s voluntary Code of Practice on marking and labelling, published in June, pushes in that direction.
People: who gets misjudged
Misjudgements land on individuals. A teacher, an editor or a recruiter may treat “watermark detected” as proof, or “no watermark” as clearance. A student who used ChatGPT to polish a paragraph, a freelancer who drafts with AI and rewrites, and a non-native speaker who uses it to fix their English all sit in different places on that line. In 2024 OpenAI itself warned that watermarking could stigmatise AI as a writing aid for non-native English speakers.
What This Means for You
- Reading the news: ask three questions of any AI watermark announcement. Is it for compliance, abuse prevention or tracing? How much survives one rewrite? Who can use the detector?
- If you write with AI: the watermark does not change how your text reads, but longer text pasted unchanged from ChatGPT in the EU will often be flagged by whoever holds the detector. If your school, employer or client has a disclosure rule, follow it.
- If you judge other people’s writing: treat a detected watermark, or the lack of one, as a lead to discuss with the writer.
If your team is deciding how to use AI in writing and what to disclose, that is the kind of policy we help set up in our AI agent and knowledge-system work. For the wider regulatory picture, see our piece on AI governance frameworks, and for another case of AI output being harvested and reused, our explainer on adversarial distillation.
Technical Marks or Honest Disclosure?
Text watermarks are useful. They give regulators a mechanism, researchers a way to measure AI text at scale, and providers a way to recognise their own output when it is reused unchanged. They are also easy to wash out, because strength costs quality. Which leaves the question this announcement cannot answer: when the signature fades with every edit, will trust in what we read rest on technical marks, or on writers being willing to say “I used AI here”?
Further reading, by search term: OpenAI textGrain watermark; Kirchenbauer green list watermark; SynthID Text; EU AI Act Article 50; AI detector false positives non-native English.
FAQ: ChatGPT and AI Text Watermarks
Does ChatGPT watermark its text?
Starting from October 2026, OpenAI is adding an invisible watermark to eligible ChatGPT and Codex text for users in the European Union, rolling out over several weeks. API customers anywhere can opt in for select models; it is off by default. The watermark is statistical: it slightly shifts which words the model chooses, so the text reads normally. OpenAI says detection tools are initially limited to approved researchers and expert organisations.
How does an AI text watermark work?
The best-known published method, from Kirchenbauer and colleagues in 2023, hashes the previous word to split the vocabulary into a green list and a red list, then gives green words a small boost so the model picks them a little more often. One word reveals nothing, but over hundreds of words the share of green words rises well above chance, and a detector that knows the rule can measure it. OpenAI has not published whether its own method, called textGrain, works this way.
Can an AI watermark be removed by editing?
Largely, yes. In OpenAI’s own test on 400-token passages, replacing 10% of words with synonyms cut detection from about 92% to 66%, and replacing 25% cut it to 17%. OpenAI also says text that is short, edited or translated may not be detected reliably. Rewriting with another model or translating and translating back weakens the signal further.
Does the EU AI Act require AI text to be watermarked?
Article 50(2) of the EU AI Act requires providers of generative AI systems, including text generators, to mark outputs in a machine-readable format so they can be detected as AI-generated, using solutions that are effective, robust and reliable as far as technically feasible. It has applied since 2 August 2026, with systems already on the market given until 2 December 2026. The law does not name a specific technique; watermarking is one way to meet it.
If no watermark is found, was the text written by a human?
No. OpenAI itself says a missing watermark does not prove human authorship. The text may come from a model without watermarking, may be too short to test, or may have been edited or translated. A detected watermark is evidence about the original text, not about who used it or why.